%20{%20:root%20{%20--deepread-stroke:%20%23E5E7EB;%20}%20}%20.dark%20{%20--deepread-stroke:%20%23E5E7EB;%20}%20%3c/style%3e%3crect%20x='40'%20y='30'%20width='220'%20height='260'%20rx='28'%20ry='28'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20fill='none'/%3e%3cpath%20d='M180%2030v52c0%2010%208%2018%2018%2018h62'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20fill='none'/%3e%3cline%20x1='70'%20y1='130'%20x2='200'%20y2='130'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3cline%20x1='70'%20y1='165'%20x2='200'%20y2='165'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3cline%20x1='70'%20y1='200'%20x2='170'%20y2='200'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3c!--%20green%20download%20arrow%20in%20bottom%20right%20corner%20--%3e%3cpath%20d='M210%20202v58'%20stroke='var(--deepread-accent)'%20stroke-width='18'%20stroke-linecap='round'/%3e%3cpath%20d='M195%20245l15%2015%2015-15'%20fill='none'%20stroke='var(--deepread-accent)'%20stroke-width='18'%20stroke-linecap='round'%20stroke-linejoin='round'/%3e%3c/svg%3e)
AI Document Processing Solutions: A Business Guide to the Category
What AI document processing solutions actually are, what manual document work still costs a business, and how to evaluate the category before you buy or build.
Every year, more vendors describe what they sell as "AI document processing." Fewer of them can say precisely what that means, or show it holding up past a demo. For a team fixing a real bottleneck, such as invoices piling up faster than anyone can key them in, claims forms still processed by hand, or freight paperwork that never quite matches a template, that gap between marketing language and actual behavior is where budget and engineering time get wasted.
Teams new to the space can get oriented with document processing automation for businesses before reading on.
This is a plain look at what AI document processing solutions are, what changed in the category recently, what manual handling costs a business, where the category gets used, how the solutions differ, and how to evaluate one before committing.
Who This Guide Is For
- Ops and finance leaders who know manual document handling is consuming capacity somewhere in the business, but have not yet mapped that to a category of software or a budget line.
- IT and procurement teams starting to scope a document automation project and trying to understand the landscape before vendor calls begin.
- Compliance and privacy officers at regulated businesses who need to know what automated document handling implies for PII exposure and audit readiness, not just processing speed.
- Engineering and product leads deciding whether this is a platform to buy or a capability to build on top of an extraction API.
If you already know you need OCR specifically, an OCR software overview focused on extraction engines and deployment types will serve you better than this guide. If you are already scoping a build and want reference architecture and integration patterns, that is a more technical conversation than this piece covers. This guide stays a level above both: the category, the business case, and how to think about the decision before you are deep in either.
What "AI Document Processing" Actually Means
Strip the marketing language and the category is doing one job: turning a document (a scan, a photo, a PDF, a fax) into data a system can act on without a person retyping it. What has changed is how well software can now do that on documents it was not specifically built for.
Older tools in this space were rules-based: templates, fixed field positions and pattern matching tuned to a specific layout. They tended to work well on documents that closely matched the ones they were tuned to, and could struggle with or misread anything that did not. RPA platforms automated the clicks and data entry around that extraction layer, but the extraction itself was often the weak point, with a bot faithfully re-keying whatever the underlying OCR got wrong.
AI-native document processing works differently. Instead of matching a document against a fixed template, it is trained to understand document structure and meaning, recognizing that a number near the words "total due" is probably an invoice total regardless of where it sits on the page or what font it uses. The machine learning behind modern OCR explains why this approach generalizes better than fixed templates.
This generally reduces how often a new template is needed when a vendor changes an invoice layout, though the degree varies by tool, document type and configuration. It is not a clean binary between systems that need retraining and ones that never do. It is also why the more useful output is not just text. It is structured, schema-mapped data, ideally with field-level signals about which values the system is unsure of, ready to drop into a database instead of a wall of characters someone still has to parse.
What Manual Document Processing Actually Costs
The business case is rarely a single dramatic number. It is the accumulation of a few costs that compound quietly:
- Ops capacity spent on re-keying, not judgment. Every hour a skilled person spends retyping an invoice or claims form is an hour not spent on the exceptions and decisions that need a human. Manual document work does not scale with volume, it just requires proportionally more headcount.
- Error rates that surface downstream, not at entry. A mistyped total or misread date rarely gets caught at the point of entry. It surfaces later as a payment discrepancy, a compliance gap or a customer service issue, when it is more expensive to fix.
- Processing delays that ripple into cash flow and service levels. Manual queues back up during volume spikes, precisely when speed matters most: month-end invoice runs, claims surges after an event and seasonal application volume.
- A compliance surface that is hard to audit. When handling is manual, "what happened to this specific document and who touched it" is often reconstructed after the fact rather than logged automatically, which is a weak position during an audit.
None of this requires an inflated statistic to make the case. The cost is structural: it is built into paying people to do work a well-built system can do in seconds, at a volume that scales without proportional headcount growth.
Where AI Document Processing Solutions Get Used
The category concentrates where document volume is high, formats are inconsistent and the manual alternative is expensive to keep running:
- Freight and logistics: bills of lading, proofs of delivery and carrier invoices that vary by carrier and rarely arrive in a consistent format.
- Banking and financial services: bank statements, loan documents and account-opening paperwork, often under strict accuracy and audit requirements. A look at AI extraction tools for fintech onboarding shows how these requirements shape tool choice.
- Healthcare: medical bills, insurance claims and patient intake forms, where PII exposure is a first-class concern, not an afterthought.
- Insurance: claims documentation and policy paperwork, where processing speed and accuracy both affect customer experience directly.
- Real estate: leases, title documents and closing paperwork, typically long, dense and inconsistent in structure from one document to the next.
The common thread is not the industry. It is the combination of volume, format inconsistency and a clear cost to the manual alternative.
How These Solutions Actually Differ
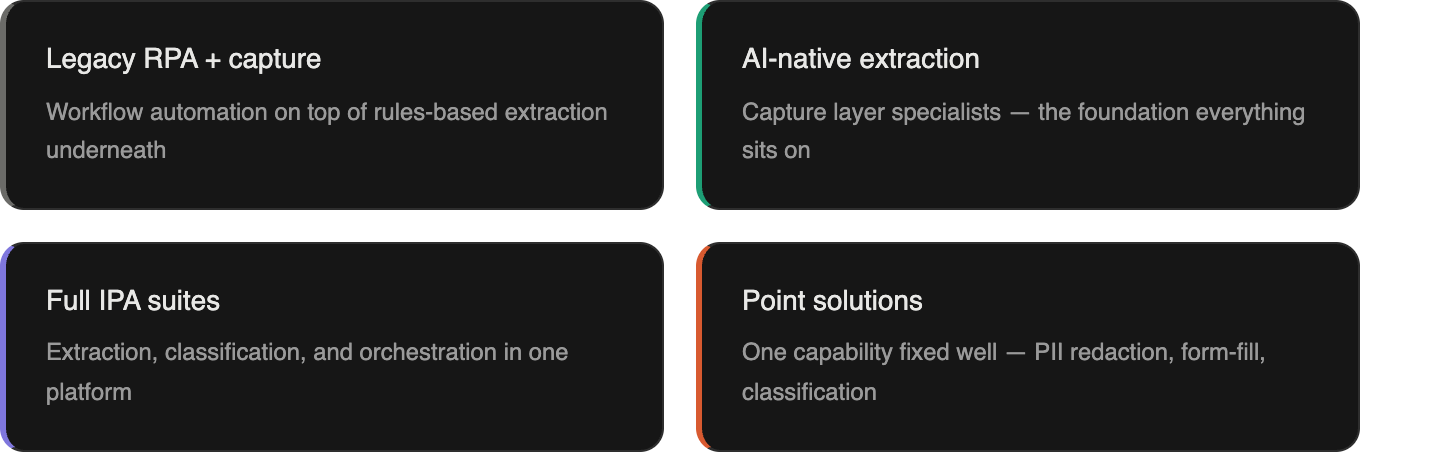
"AI document processing solution" covers a wider range of products than the label suggests:
- Legacy RPA platforms with document capture bolted on. These automate the workflow (routing, approvals, system updates) around an extraction layer that is often still rules-based underneath. They can look sophisticated in a demo on a clean sample and still struggle on the messy, real version.
- AI-native extraction platforms and APIs. These specialize in the capture layer itself, reading varied, messy or handwritten documents and returning structured output, often without a model retrained for every new document type. This is the layer everything else in the category depends on.
- Full intelligent process automation suites. These combine extraction, classification, validation, exception routing and orchestration in one platform, sometimes with an agentic decisioning layer on top. They are useful when a team wants an end-to-end platform rather than assembling one, and the trade-off is usually a longer implementation timeline and less control over any single stage.
- Point solutions for a specific problem. PII detection, form-fill automation and document classification are increasingly available as standalone capabilities. For example, automated document redaction tools cover the PII side without a full suite.
None of these is categorically better. The right fit depends on whether your documents are standard, whether you have engineering resources to build with, and whether you need a full workflow platform or one specific capability fixed well. How RPA, IDP and full IPA relate to each other is worth understanding in more depth if you are at the build-scoping stage rather than the category-mapping stage this guide is written for.
PII, Compliance, and What the EU AI Act Actually Requires
Compliance and privacy teams evaluating this category often start from an assumption that is more restrictive than reality. Regulatory frameworks like the EU AI Act apply obligations based on risk classification and specific use case, not a blanket rule that every document-processing workflow is automatically high-risk. A standard invoice-extraction pipeline is treated differently from a system making automated decisions about credit, employment or identity verification, which face stricter requirements. Obligations are also phasing in over several years rather than applying all at once, and the Digital Omnibus pushed the high-risk rules for stand-alone systems to 2 December 2027 and for systems embedded in regulated products to 2 August 2028. Confirm current dates with counsel.
The practical takeaway is to check whether your specific use case and document types fall into a higher-risk category before assuming you need extensive explainability tooling from day one. That said, a few things are worth building into any document processing implementation regardless of current classification, since regulatory scope in this area tends to expand over time:
- Audit logging by default: what was extracted, what was flagged and who reviewed it, reconstructable on demand.
- PII detection and handling as a first-class step, not bolted on after extraction.
- Decision traceability: for any document, the ability to explain why it was auto-processed or routed to a human.
If PII handling is still a manual review step in your process today, that is usually the clearest sign the tool you are evaluating was not built with compliance as a core requirement.
How to Evaluate an AI Document Processing Solution
Before you are deep in a vendor comparison, a handful of questions do most of the filtering work:
- Does it hold up on your actual documents, not a clean demo set? Bring your messiest, most representative documents to any evaluation.
- Is the accuracy claim independently checkable? Ask what the number was measured against, whether the methodology is public and whether you can verify it yourself.
- What happens to the documents it cannot process confidently? A system that flags uncertain fields for review is more trustworthy than one with a similar accuracy score that fails silently.
- Does it fit how you will integrate it? A full platform with a UI suits a team that wants to buy something finished. A schema-driven API with asynchronous processing suits a team building document handling into an existing product or pipeline.
- What does compliance require for your use case? Not the maximum standard, but the one that applies to your document types and risk classification.
This is the same filter, at a higher level, that applies whether you end up buying an accounts-payable platform, an enterprise IDP suite or building a custom workflow on a document extraction API. The specifics differ by category and are worth a closer look once you know which decision you are making.
Where the Extraction Layer Fits
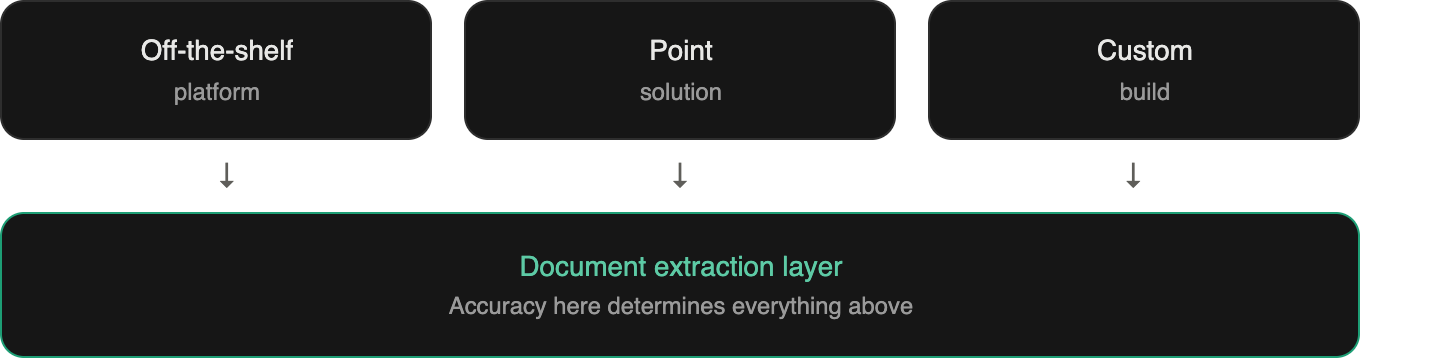
Whichever direction a team goes (buying a platform, adopting a point solution or building custom), everything downstream depends on one thing being accurate: the extraction layer. A workflow, an approval chain or an agentic decisioning step built on inaccurate extraction just automates the production of errors faster than a person would have made them.
DeepRead is one example built for that layer. It is a schema-driven extraction API that returns the page, bounding box and source text for each field, and flags uncertain fields with needs_review and a review_reason rather than a numeric confidence score. A review interface for flagged fields is included on every plan, and a failed job costs nothing. Jobs are processed asynchronously and checked by polling, with webhooks available on the Standard and Enterprise plans.
For teams with strict infrastructure needs, processing defaults to US East, there is no self-hosted option, and no plan includes a BAA. Whatever tool you test, apply the same standard: ask for a method and dataset you can check yourself.
Conclusion
"AI document processing" has become broad enough as a label that it no longer tells a buyer much on its own. What separates a solution that removes manual work from one that adds a nicer interface on top of it comes down to a few specifics: how it performs on your real documents rather than a demo, what happens to the documents it cannot process confidently, whether the accuracy claim is something you can check yourself, and whether the deployment shape (full platform, point solution or extraction API to build on) fits how your team works.
None of that requires picking a vendor today. It requires knowing which category you are shopping in, and testing the claim that matters most, accuracy on your documents, before anything else.
FAQ
What is the difference between AI document processing and traditional OCR?
Traditional OCR reads characters and returns text. AI document processing goes further: it classifies the document, understands what each piece of text represents and returns structured, schema-mapped data rather than a wall of unstructured text someone still has to parse.
Is AI document processing the same as RPA?
No, though they are often bundled together. RPA automates repetitive actions based on fixed rules and can become brittle when inputs change. AI document processing, often called IDP, handles the harder problem of reading variable, messy or unfamiliar document formats. Many platforms combine both, layering workflow automation on top of an extraction layer.
How much does an AI document processing solution cost?
It varies by category. SMB-focused platforms often have published self-serve pricing, enterprise suites are typically quote-based with implementation costs on top, and developer APIs are frequently usage-based with a free tier for testing. Evaluate cost alongside implementation timeline and accuracy on your actual documents, not in isolation.
Do I need developers to implement an AI document processing solution?
Not necessarily. Off-the-shelf platforms with a UI are built for non-technical teams to configure directly. Building on a document extraction API requires engineering resources, but gives you control over schema, integration and workflow logic that a fixed platform template does not offer.
How is document extraction accuracy actually measured?
Rigorously, it should be checkable: the same set of documents run through multiple engines, compared against a manually verified ground truth, with the methodology and results published rather than asserted. If a vendor's accuracy claim does not specify what it was measured against, ask directly.
Does the EU AI Act mean every document processing workflow needs explainability tooling?
No. Obligations are risk- and use-case-based, not a blanket requirement, and they are phasing in over several years, with the high-risk rules now set for 2 December 2027 (stand-alone systems) and 2 August 2028 (embedded systems). Confirm current dates with counsel. A standard document-extraction workflow is treated differently from a system making automated decisions about credit, employment or identity. It is still worth building audit logging and traceability from the start, since regulatory scope in this area continues to evolve.
More articles
Semantic Document Search: How It Works and How to Build It with Embeddings
How semantic document search works, plus a Python build: extract, chunk, embed, and search, with a tested keyword, semantic, and hybrid comparison.
How to Parse a PDF File: Methods, Libraries, and Tools
Parse a PDF file in Python with tested code: check the text layer, extract text and tables, OCR scanned pages, and compare pypdf, pdfplumber, and PyMuPDF