%20{%20:root%20{%20--deepread-stroke:%20%23E5E7EB;%20}%20}%20.dark%20{%20--deepread-stroke:%20%23E5E7EB;%20}%20%3c/style%3e%3crect%20x='40'%20y='30'%20width='220'%20height='260'%20rx='28'%20ry='28'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20fill='none'/%3e%3cpath%20d='M180%2030v52c0%2010%208%2018%2018%2018h62'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20fill='none'/%3e%3cline%20x1='70'%20y1='130'%20x2='200'%20y2='130'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3cline%20x1='70'%20y1='165'%20x2='200'%20y2='165'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3cline%20x1='70'%20y1='200'%20x2='170'%20y2='200'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3c!--%20green%20download%20arrow%20in%20bottom%20right%20corner%20--%3e%3cpath%20d='M210%20202v58'%20stroke='var(--deepread-accent)'%20stroke-width='18'%20stroke-linecap='round'/%3e%3cpath%20d='M195%20245l15%2015%2015-15'%20fill='none'%20stroke='var(--deepread-accent)'%20stroke-width='18'%20stroke-linecap='round'%20stroke-linejoin='round'/%3e%3c/svg%3e)
Enterprise-Scale Document Automation Software: What Actually Changes at Scale
Learn how to evaluate enterprise document automation software, compare platforms vs APIs, manage compliance, integrations, and scale successfully.
A document automation tool that performs well in a pilot with fifty sample documents does not automatically perform the same way when it processes two hundred thousand documents a month across twelve business units in six countries. The extraction technology is not usually what breaks first. It is everything around it: exception queues with no clear owner, integration points that assumed one ERP instance instead of four, and a procurement process that takes longer than the implementation itself.
This is a guide to what changes when document automation has to operate at enterprise scale, what to evaluate that a standard feature comparison misses, and how to think about the choice between an enterprise platform and building on a document extraction API when your documents fit neither cleanly.
Who This Guide Is For
- IT and operations directors at banking, healthcare, insurance or real estate organizations evaluating platforms such as Rossum or UiPath Document Understanding, who want to understand what separates them beyond the sales deck.
- Enterprise architects and engineering leads scoping whether an off-the-shelf platform fits the organization's document mix, or whether a custom build on an extraction API is the more durable path.
- Compliance and information security teams who get pulled into evaluations late and need a clear list of what to screen for before a vendor gets near production data.
- Procurement and finance stakeholders trying to understand why timelines and costs vary so widely between vendors.
If you are earlier in the process and still mapping the category, this overview of AI document processing solutions covers that ground. This guide assumes you already know you are buying at enterprise scale.
What "Enterprise Scale" Actually Changes
Vendors use "enterprise-ready" almost as loosely as "AI-powered." What changes at scale is more specific than a bigger number on an invoice:
- Volume exposes exception handling, not just accuracy. A tool that is 95% accurate sounds fine at a thousand documents a month. At two hundred thousand a month, the remaining 5% is ten thousand documents needing review, and if nobody planned the staffing for that queue, the automation has relocated the bottleneck instead of removing it. The trade-offs are laid out in this comparison of AI processing versus manual review.
- Multi-entity, multi-currency, multi-region complexity. Large organizations rarely run one instance of one ERP. Automation that assumes a single entity, currency or region can break against subsidiaries and cross-border operations, each with different document formats and compliance requirements.
- Integration depth, not just integration existence. A vendor listing a Salesforce integration on a feature page is different from a native connector that handles your configuration, custom fields and data volume without a professional services engagement.
- Governance and audit requirements that assume scrutiny. In regulated industries, being able to reconstruct what happened to a document is assumed, and it needs to be true by default rather than something IT builds afterward.
- A procurement and implementation timeline measured in quarters. Security review, legal review, data processing agreements and phased rollout all add time before a platform is live, and that timeline is frequently the deciding factor between two vendors of comparable capability.
The Enterprise Document Automation Landscape
At the enterprise end of the category, a handful of products come up repeatedly. Rossum and UiPath Document Understanding position themselves around document intelligence inside a broader automation suite, aimed at large organizations with implementation budgets. Note that Coupa announced its acquisition of Rossum on May 12, 2026, so Rossum is now part of a procurement and spend platform, and teams comparing options may also want to look at Rossum alternatives.
Cloud providers offer extraction as part of a much larger platform. AWS Textract and Google Document AI appeal to enterprises already standardized on that cloud, though they are general-purpose extraction services rather than document-automation platforms with built-in workflow and review tooling.
This list reflects how vendors position themselves publicly, not an independent benchmark. Extraction accuracy is the one claim in this category that can be measured against a common dataset, and it is worth asking any vendor, platform or API, whether their number is something you can verify yourself. Independent comparisons such as an LLM OCR accuracy leaderboard show what that kind of check looks like.
What Enterprise Buyers Should Actually Evaluate
A feature checklist gets a vendor through the first call. What separates deployments that work from ones that stall:
- Touchless processing rate on your document mix and volume, not a pilot batch of clean samples. Ask what happens to the share that is not processed touchless, and who owns reviewing it.
- Security certifications, confirmed directly. SOC 2, ISO 27001 and GDPR support are standard asks. Get current documentation instead of relying on an "enterprise-grade" label.
- SSO, SCIM and access control depth that matches how your organization manages identity and permissions across business units.
- Data residency and cross-border handling, especially for multi-region operations under different regulatory regimes.
- Multi-entity and multi-currency support confirmed against your real organizational structure, not a generic demo.
- Integration depth with your systems, tested against your configuration, not just a logo on an integrations page.
- Uptime SLAs and support commitments appropriate to a production system your operations depend on.
- A realistic implementation timeline, sourced from the vendor's recent deployments of comparable complexity. A framework for weighing these factors appears in this guide on how to choose a document automation tool.
- Total cost of ownership, including professional services, integration work and ongoing exception-handling headcount, not just the license or per-document rate.
The single most useful question to ask any vendor, platform or API, is what an evaluation on your actual documents, at close to your actual volume, looks like before you sign anything. A vendor confident in its accuracy will make that easy.
Compliance and Governance at Enterprise Scale
Regulated enterprises often assume the compliance bar is higher and more uniform than it is. Frameworks such as the EU AI Act apply obligations based on risk classification and use case, not a blanket rule that every document automation deployment is high-risk. A standard extraction workflow is treated differently from a system making automated decisions about credit, employment or identity, and the obligations phase in over several years.
Even so, a few things are worth requiring from any vendor regardless of current classification, because retrofitting them after a multi-business-unit rollout is far more expensive:
- Audit logging by default across every business unit and document type, reconstructable on demand without a support ticket.
- Review flags and their reasons retained, not used transiently at decision time and then discarded.
- Decision traceability at the individual document level. For any document, in any entity, you should be able to show why it was auto-processed or routed to review, and where on the source page each value came from.
- PII detection as a first-class step, especially for healthcare, insurance and banking documents where sensitive data is the norm.
If a vendor's answer to any of these is that they would need to build a custom report, treat that as a real signal about production support.
Build vs. Buy at Enterprise Scale
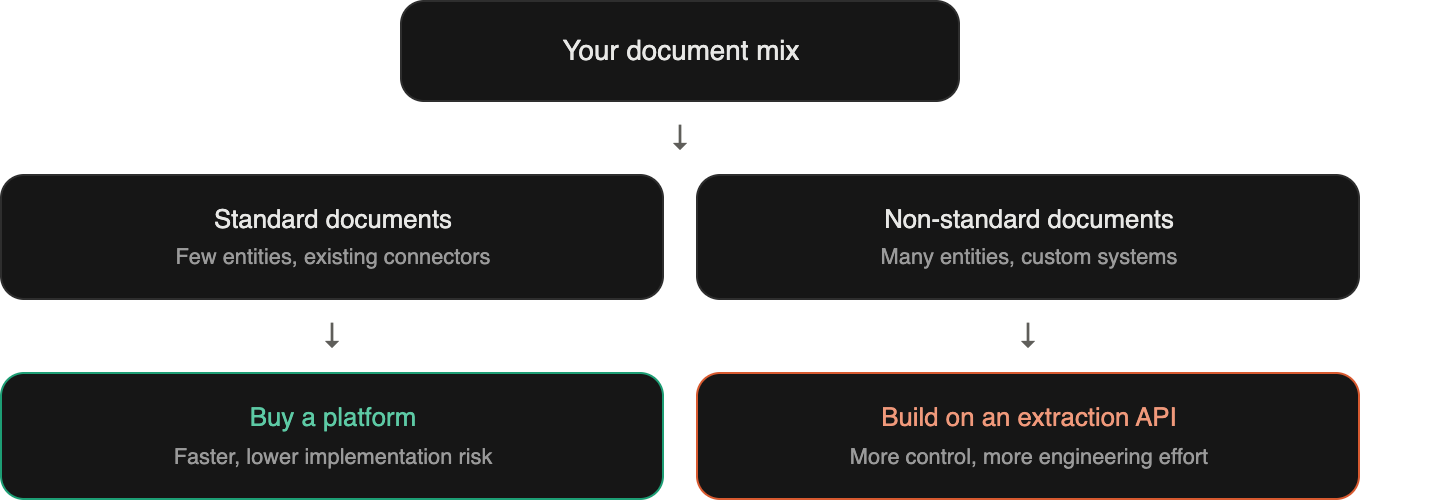
Every platform in this category is built around a reasonably standard document workflow. Most enterprises should buy rather than build, because an established platform with proven implementation experience is almost always faster and lower-risk than building equivalent tooling.
The gap shows up for organizations whose documents do not fit a standard template: non-standard formats across business units, legacy or heavily customized ERP systems without a clean native connector, or document types specific enough that no platform supports them. For these organizations the constraint is usually not the platform's workflow logic. It is the extraction layer underneath, tuned for standard formats rather than the organization's actual documents.
Enterprise engineering teams sometimes route around a monolithic platform and build a custom workflow on top of a document extraction API, feeding structured, schema-driven data into existing enterprise systems. At enterprise volume, that depends on two things many extraction layers handle poorly: asynchronous processing that holds up under large batch runs, and delivery options that scale across many downstream consumers, whether by webhook or by polling, without becoming an operational burden of their own.
Where the Extraction Layer Fits
Under a platform or a custom build, the same dependency holds: nothing downstream is more accurate than the extraction feeding it. A workflow with sophisticated routing and approval logic built on unreliable extraction just produces confidently wrong data at enterprise volume.
For organizations weighing a custom build, or simply pressure-testing a platform's accuracy claim, DeepRead is one example of an extraction layer to test. It is a developer-first OCR and document AI API, not a workflow platform, so routing, approvals and system integration are yours to build. Extraction is schema-driven, and each field returns its page, bounding box and source text so a reviewer can check it against the original. Fields that need a human look are flagged with needs_review and a review_reason, and a review interface for flagged fields is available on every plan. Jobs run asynchronously and return a job ID you can poll, with webhook delivery on the Standard and Enterprise plans, and a failed job costs nothing.
Enterprise buyers should also weigh the limits. Processing defaults to US East, there is no self-hosted option, and no BAA is offered on any plan, so regulated healthcare workloads or strict residency requirements may rule it out. Free and Standard plans retain documents for up to three years, which is worth reconciling with your own retention policy.
Conclusion
Enterprise-scale document automation fails less often because the extraction technology is weak and more often because the surrounding requirements were not built into the evaluation: exception ownership at volume, multi-entity support, integration depth, governance and a realistic implementation timeline. The vendors at this end of the category are capable across the board. What separates a deployment that works from one that stalls in a pilot is whether it was evaluated against your real documents, volume and organizational structure.
Whether the answer is an established platform or a custom build on an extraction API, the questions are the same. Does it hold up at your scale, can you verify the accuracy claim yourself, and does the compliance and governance model match what your organization will be audited against?
Frequently Asked Questions
What makes document automation software "enterprise-scale" versus standard?
Volume is only part of it. Enterprise scale implies multi-entity and multi-currency support, integration depth with complex or legacy systems, governance and audit requirements that assume regulatory scrutiny, and security controls that match how large organizations manage identity and compliance.
Is Rossum or UiPath Document Understanding better for enterprise document automation?
Both are established, enterprise-oriented products, and the better fit depends on your document types, existing systems and implementation resources rather than a general ranking. Rossum is now owned by Coupa, which may matter if procurement and spend management are part of your plan. Evaluate both against your own documents and integration requirements.
How long does enterprise document automation implementation take?
Usually longer than the first sales conversation suggests. Security review, legal and compliance review and phased rollout across business units typically add months beyond the technical work. Ask for timelines from comparable recent deployments.
Does the EU AI Act require extensive explainability for enterprise document automation?
Not universally. Obligations are risk- and use-case-based, and they phase in over several years. A standard extraction workflow is treated differently from a system making automated decisions about credit, employment or identity. Enterprises should still build in audit logging and decision traceability by default, since regulatory scope continues to expand.
When does it make sense for an enterprise to build instead of buying a platform?
When document formats, ERP configuration or business-unit structure do not fit any platform's standard template, which is common with legacy systems, heavily customized ERPs and industry-specific documents. An accurate, async-capable extraction API as the foundation for a custom workflow can then outperform forcing documents into an off-the-shelf template.
What is the highest hidden cost in enterprise document automation?
Exception-handling headcount. The accuracy number determines how many documents fall into manual review, and at enterprise volume even a small exception rate becomes a meaningful ongoing staffing cost if it was not planned during evaluation.
More articles
Semantic Document Search: How It Works and How to Build It with Embeddings
How semantic document search works, plus a Python build: extract, chunk, embed, and search, with a tested keyword, semantic, and hybrid comparison.
How to Parse a PDF File: Methods, Libraries, and Tools
Parse a PDF file in Python with tested code: check the text layer, extract text and tables, OCR scanned pages, and compare pypdf, pdfplumber, and PyMuPDF