%20{%20:root%20{%20--deepread-stroke:%20%23E5E7EB;%20}%20}%20.dark%20{%20--deepread-stroke:%20%23E5E7EB;%20}%20%3c/style%3e%3crect%20x='40'%20y='30'%20width='220'%20height='260'%20rx='28'%20ry='28'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20fill='none'/%3e%3cpath%20d='M180%2030v52c0%2010%208%2018%2018%2018h62'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20fill='none'/%3e%3cline%20x1='70'%20y1='130'%20x2='200'%20y2='130'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3cline%20x1='70'%20y1='165'%20x2='200'%20y2='165'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3cline%20x1='70'%20y1='200'%20x2='170'%20y2='200'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3c!--%20green%20download%20arrow%20in%20bottom%20right%20corner%20--%3e%3cpath%20d='M210%20202v58'%20stroke='var(--deepread-accent)'%20stroke-width='18'%20stroke-linecap='round'/%3e%3cpath%20d='M195%20245l15%2015%2015-15'%20fill='none'%20stroke='var(--deepread-accent)'%20stroke-width='18'%20stroke-linecap='round'%20stroke-linejoin='round'/%3e%3c/svg%3e)
Intelligent Document Workflow Automation: How to Actually Build It
How to actually build intelligent document workflow automation - architecture, integration patterns, compliance design, and common implementation pitfalls.
Introduction
Most content on intelligent document workflow automation explains what it is. This guide is about what happens after you have decided to build one: the architecture decisions, integration patterns, and implementation choices that determine whether a project holds up in production or stalls between the pilot and the rollout. For examples of how organizations apply the technology, see this overview of how organizations use AI for document processes.
If you already know the difference between RPA, IDP and IPA, skip to the reference architecture. The short version is this. RPA automates repetitive, rule-based tasks and can become brittle when inputs, layouts, or interfaces change. IDP adds AI and machine learning to handle documents in variable formats, and it is designed to extract from layouts it was not explicitly trained on, although how well it does depends on the tool, the document type, and the configuration. IPA is the broader layer that combines both with orchestration and decision logic across a whole workflow. The capabilities that separate these layers are broken down in this piece on the key features of AI document workflow automation.
Reference Architecture
Strip away the vendor branding and almost every implementation is built from the same six components:
- Capture. Documents arrive from email, upload, scan or API, in whatever format they come in.
- Classification. The system identifies what kind of document it is looking at before deciding how to process it.
- Extraction. OCR and ML models pull structured fields out of the document, typically through a document processing API.
- Validation. Extracted data is checked against business rules such as arithmetic checks, formats and required fields, and fields the engine is unsure about are marked.
- Exception routing. Anything flagged, or that fails validation, goes to a human reviewer instead of being processed blind.
- Orchestration. Validated data is written into downstream systems, triggering whatever comes next.
The branch back to human review is the part most implementations get wrong, either by skipping it or by bolting it on as an afterthought instead of designing it in from the start.
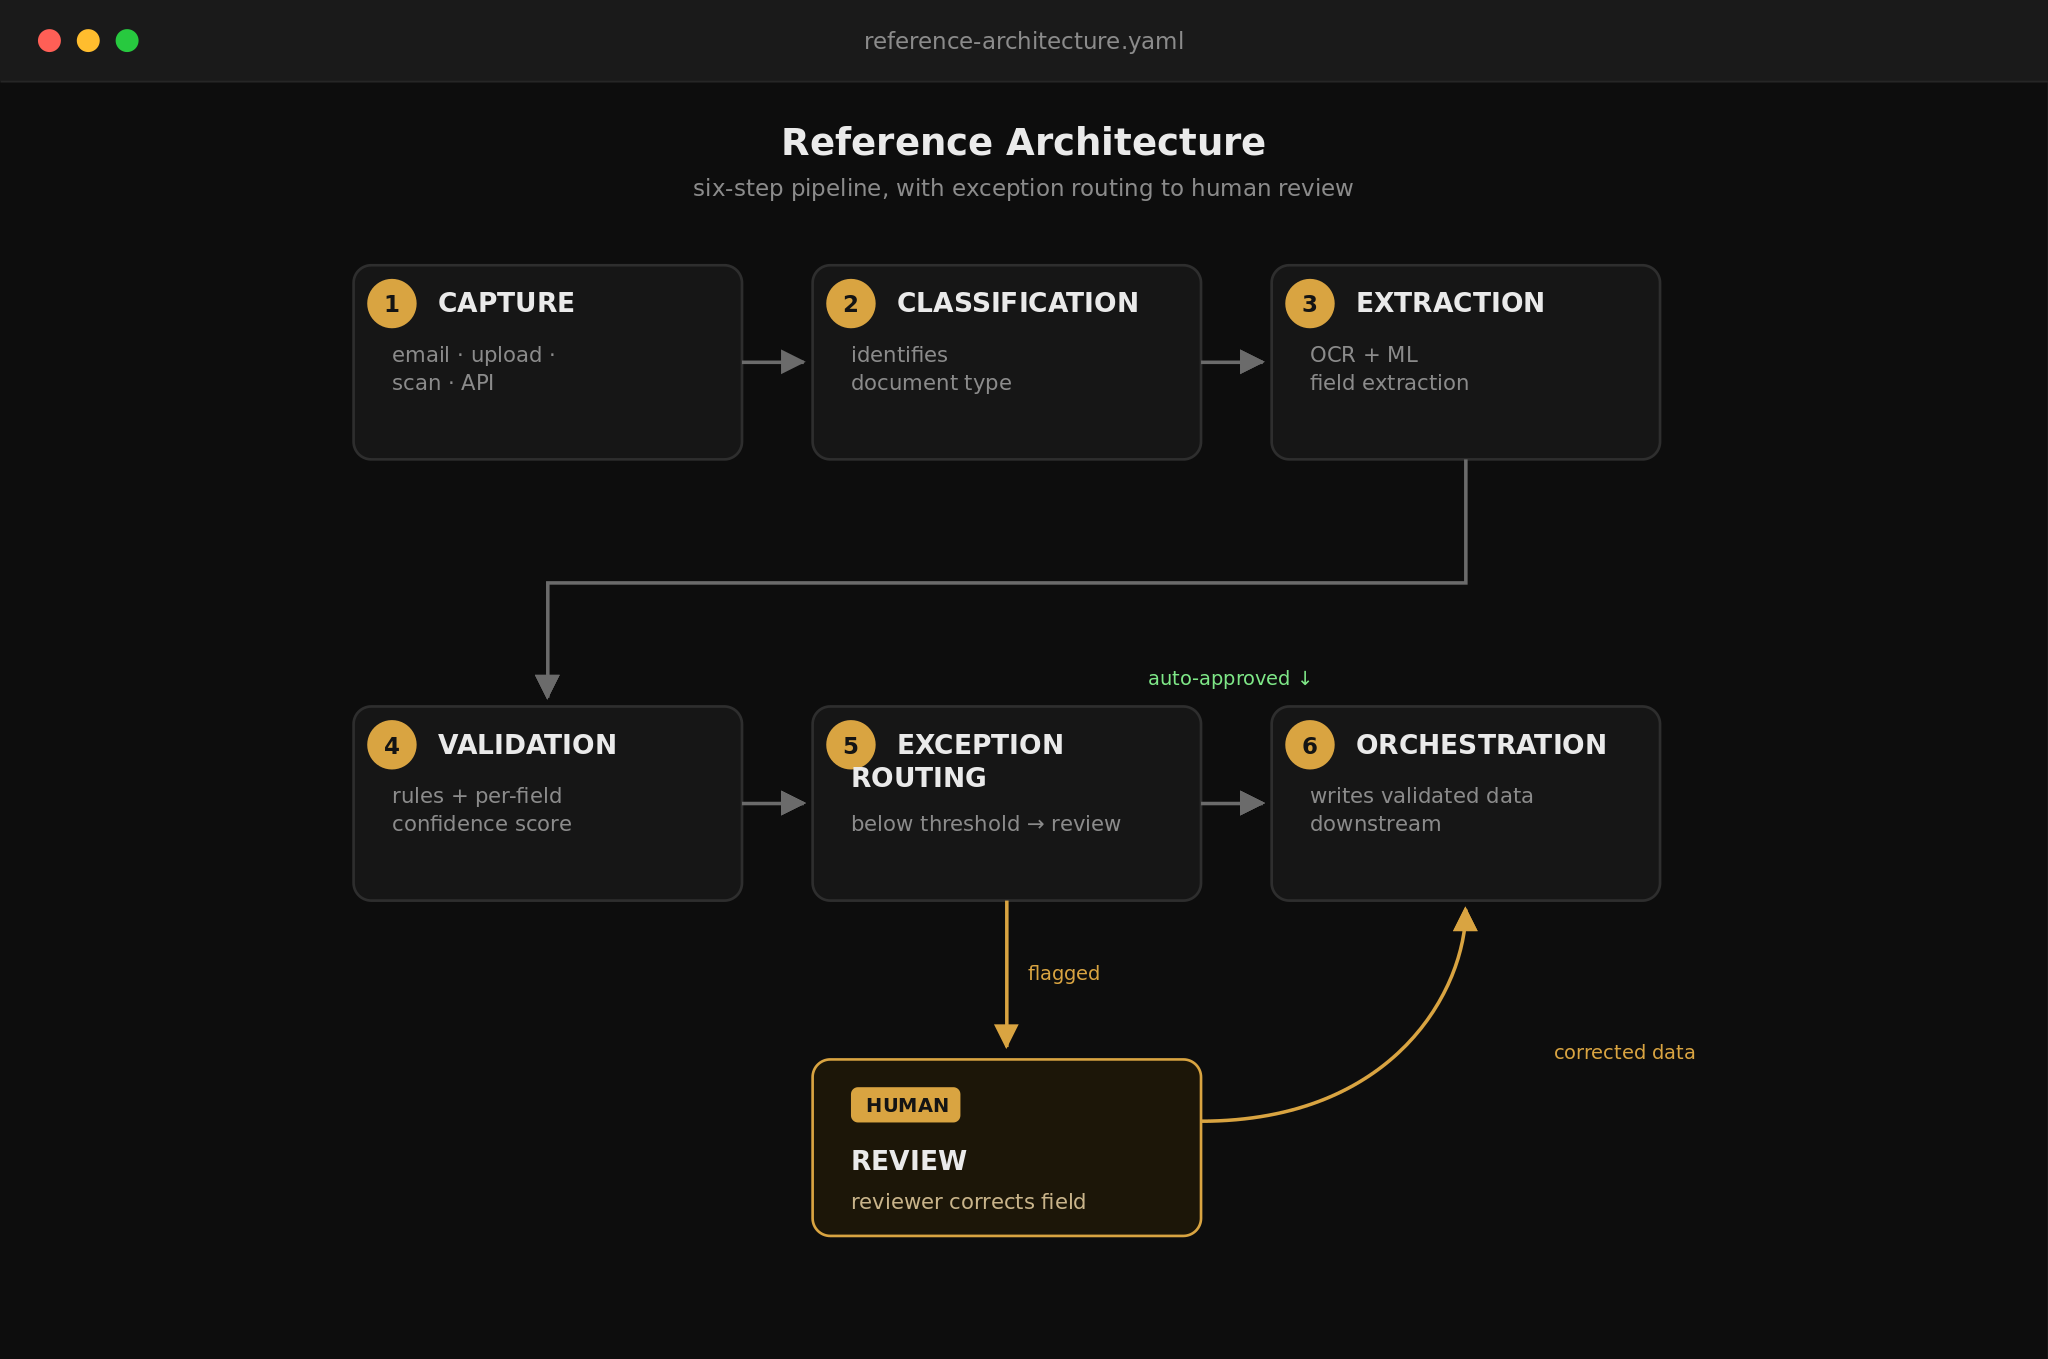
Steps one to three are largely commoditized, and most modern extraction engines handle common document types reasonably well. Steps four to six are where implementations differentiate, and where most of the engineering effort in a real build goes.
The Decisions That Determine Whether This Works
Synchronous vs. Asynchronous Processing
If you process documents one at a time as they arrive, synchronous calls are simpler to build. If you process batches, such as end-of-day invoice runs or bulk claims intake, synchronous calls will block your application and can time out on large volumes. Asynchronous processing, with a webhook callback or a status check, is the pattern that scales past small volumes. Design for it from day one rather than retrofitting it after a pilot succeeds, as covered in this article on scaling data capture with document AI.
Review Thresholds
Every extraction engine gives you some signal about which fields to trust, whether that is a numeric score, a review flag or a validation failure. The rule for "auto-approve" versus "route to human review" is a business decision, not a technical one. Set it too loose and errors slip through. Set it too strict and your exception queue fills with fields that were actually correct. Tune the rule against your real documents during the pilot instead of setting it once, since document mix and vendor behavior shift over time.
Where Human Review Actually Sits
Exception routing only works if a real person, with real bandwidth, reviews flagged items in a reasonable window. Teams often design the routing correctly and then discover the queue has no owner, or that the person assigned has no time budgeted. This is an organizational decision as much as a technical one, and it needs an owner before launch. Well-designed review is also what lets automation reduce errors rather than hide them, a point developed in this piece on how AI automation minimizes human error in document handling.
Schema Stability
Downstream systems such as ERP, CRM and case management expect a consistent data shape. If your extraction output changes through new fields, renamed fields or restructured nesting, every integration that consumes it has to change too. Decide early whether your extraction layer supports versioned or backward-compatible schemas, because this is expensive to fix once several systems depend on a specific shape.
Feedback From Human Corrections
When a reviewer corrects a flagged field, does that correction improve future extraction, or does it only fix that one document? Systems that treat every correction as a one-off do not improve over time. Confirm with any extraction provider how corrections are used before you build around it.
Integration Patterns
Three patterns cover most real implementations:
- Webhook-driven. The extraction layer processes a document asynchronously and calls an endpoint you control when it finishes, delivering the structured result directly. This is the lowest-latency, lowest-overhead pattern for most production pipelines, because your system reacts the moment data is ready. Check which plans of your provider include webhooks.
- Polling. Your system periodically checks a status endpoint for completed jobs. It is simpler to implement in some environments and a reasonable choice for a pilot or for plans without webhooks, but it adds latency and unnecessary load at higher volumes.
- Event queue-based. For teams already running message queues such as SQS or Kafka, extraction results can be published as events that downstream consumers subscribe to. This decouples the extraction layer from any single system and suits organizations with many consumers of the same data, but the extra infrastructure is rarely worth it for a first implementation.
For most teams building their first workflow, webhook-driven is the right default. It is simple enough to build quickly and scales further than most first projects need.
If You Are Adding Agentic Decisioning on Top
A newer layer appears in more implementations. Instead of validated document data going straight to a person or a fixed rule, it is handed to an AI agent that reasons over it and takes further action, such as flagging, prioritizing or, for well-defined tasks, acting autonomously.
The implementation implication is direct: an agent's decisions are only as reliable as the document data it reasons over. That makes extraction and review flagging more important, not less, because an agent working from inaccurate or poorly flagged data will make confident, wrong decisions faster than a human would. Do not add an agentic layer before the extraction and exception-handling foundation is solid.
Compliance Requirements to Design In From Day One
It is worth being precise rather than assuming the worst or the least. Frameworks such as the EU AI Act apply obligations based on risk classification and use case, not a blanket rule that every document workflow is high-risk. A general invoice-extraction pipeline is treated differently from a system making automated decisions about credit, employment or identity verification, which typically face stricter requirements. The obligations also phase in over several years.
In practice, check whether your use case and document types fall into a higher-risk category before assuming you need extensive explainability tooling. Regardless of current classification, build these in from the start, since regulatory scope tends to expand and retrofitting is far more expensive:
- Audit logging by default: what was extracted, what was flagged, who reviewed it and when, reconstructable on demand.
- Review signals retained, including flags, their reasons and any scores your engine provides, not used transiently and then discarded.
- Decision traceability: for any document, you can answer why it was auto-processed or routed to review, and where on the source page each value came from.
Common Implementation Pitfalls
- Scoping the pilot too broadly. "Automate all AP documents" fails more often than "automate one invoice format from three known vendors." Narrow the scope, prove the numbers, then expand.
- Treating exception handling as an afterthought. With no owner and no time budget for the review queue, the automation just shifts the bottleneck.
- Assuming pilot accuracy holds at scale. A pilot on curated documents does not guarantee the same accuracy on the messier mix production sees.
- No plan for schema evolution. The first version of your schema is rarely the last.
- Ignoring the feedback loop. If corrections do not feed back, you pay for review labor indefinitely.
- Adding orchestration complexity too early. Agentic decisioning and multi-system orchestration are easier to add once extraction and exception handling are proven.
Where the Document Intelligence Layer Fits
Everything in this architecture, the decisions above and the integration patterns, depends on step three being reliable. A workflow layer built on inaccurate extraction just automates the production of errors faster.
DeepRead is a developer-first OCR and document AI API for that layer, designed to plug into the architecture described here rather than require you to build around a closed platform. Extraction is schema-driven, and every field returns its page, bounding box and source text, which supports the traceability described above. Fields that need a human look are flagged with needs_review and a review_reason instead of a numeric score, and a review interface for flagged fields is available on every plan. Jobs run asynchronously and return a job ID you can poll, with webhook delivery on the Standard and Enterprise plans, and a failed job costs nothing. Processing defaults to US East, and there is no self-hosted option.
Whatever engine you choose, extraction accuracy is the one claim in this architecture worth checking yourself on your own documents before you build on top of it.
Implementation Checklist
- Extraction accuracy validated on your actual documents, not a demo set, before committing to an architecture
- Async support confirmed, and webhook availability confirmed for your plan, if you process anything beyond low one-at-a-time volume
- Review rule tuned during the pilot, not set once and forgotten
- Human review queue has a named owner with allocated time before launch
- Schema versioning or backward-compatibility plan in place before multiple systems depend on the output
- Audit logging and decision traceability built in, regardless of current regulatory classification
- Feedback loop from corrections confirmed: does the system improve, or does every correction stay a one-off?
Conclusion
Intelligent document workflow automation is not difficult to explain. It is difficult to implement well. The architecture is fairly consistent across the category: capture, classify, extract, validate, route exceptions, orchestrate. What separates a project that works in production from one that stalls after the pilot is rarely that high-level design. It is the decisions underneath: how review rules are tuned, who owns the exception queue, whether the schema can evolve, and whether corrections make the system smarter over time.
Get the extraction layer right first. Everything built on top of it, including orchestration, agentic decisioning and compliance logging, inherits its accuracy for better or worse. If you are at the architecture stage, DeepRead's Free plan is enough to test extraction and review flagging on your own document mix before you commit engineering time, though webhook delivery needs Standard, so use polling while you test.
Frequently Asked Questions
What is the difference between building this myself and buying a platform?
Buying gets you a faster start with a fixed workflow shape. Building gives you control over schema, integration patterns and how exception handling fits your process. It is worth it when your documents or workflow do not fit a standard platform's template, and not worth it if they do.
Should I use webhooks or polling for document processing results?
Webhooks for most production use cases, provided your plan supports them. Polling adds latency and load as volume grows, but it is a fine choice for a pilot or on plans without webhook delivery.
How do I set the right threshold for auto-approval versus human review?
There is no universal number. It depends on your risk tolerance and document mix. Start conservative during the pilot, with more items routed to review than you expect to need long term, measure how many flagged items turn out to be correct, and adjust the rule from that data.
Does the EU AI Act require explainability for all document automation?
No. Obligations are risk- and use-case-based, and they phase in over several years. A standard extraction workflow is treated differently from a system making automated decisions about credit, employment or identity. It is still worth building in audit logging and traceability.
What is the most common reason these implementations fail after a successful pilot?
Scope creep at rollout, an exception queue with no real owner, or a schema that was not designed to change. These are organizational and architectural issues, not accuracy problems.
More articles
Semantic Document Search: How It Works and How to Build It with Embeddings
How semantic document search works, plus a Python build: extract, chunk, embed, and search, with a tested keyword, semantic, and hybrid comparison.
How to Parse a PDF File: Methods, Libraries, and Tools
Parse a PDF file in Python with tested code: check the text layer, extract text and tables, OCR scanned pages, and compare pypdf, pdfplumber, and PyMuPDF