%20{%20:root%20{%20--deepread-stroke:%20%23E5E7EB;%20}%20}%20.dark%20{%20--deepread-stroke:%20%23E5E7EB;%20}%20%3c/style%3e%3crect%20x='40'%20y='30'%20width='220'%20height='260'%20rx='28'%20ry='28'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20fill='none'/%3e%3cpath%20d='M180%2030v52c0%2010%208%2018%2018%2018h62'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20fill='none'/%3e%3cline%20x1='70'%20y1='130'%20x2='200'%20y2='130'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3cline%20x1='70'%20y1='165'%20x2='200'%20y2='165'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3cline%20x1='70'%20y1='200'%20x2='170'%20y2='200'%20stroke='var(--deepread-stroke)'%20stroke-width='16'%20stroke-linecap='round'/%3e%3c!--%20green%20download%20arrow%20in%20bottom%20right%20corner%20--%3e%3cpath%20d='M210%20202v58'%20stroke='var(--deepread-accent)'%20stroke-width='18'%20stroke-linecap='round'/%3e%3cpath%20d='M195%20245l15%2015%2015-15'%20fill='none'%20stroke='var(--deepread-accent)'%20stroke-width='18'%20stroke-linecap='round'%20stroke-linejoin='round'/%3e%3c/svg%3e)
OCR Software Overview: How It Works, the Different Types, and What to Look For
Discover how OCR software works, explore different OCR types, key features, benefits, and what to consider when choosing the right solution.
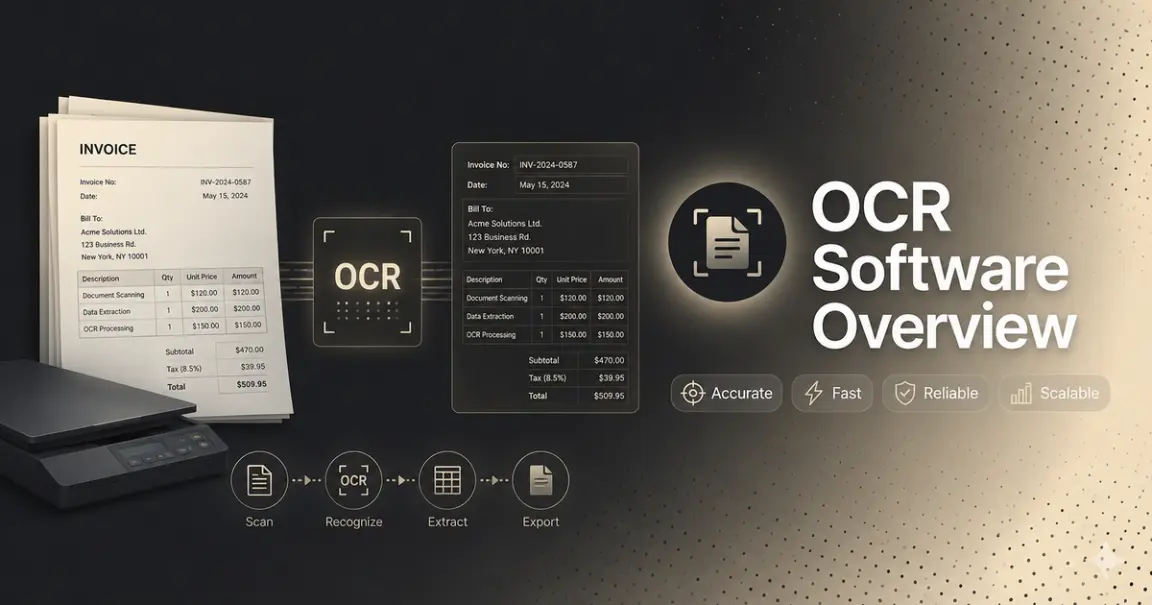
Every OCR tool claims to "read" documents. Few explain what that means, why two OCR products can process the same invoice and produce wildly different results, or why the right OCR software depends heavily on who you are and what you are trying to fix.
Manual document processing compresses margins in freight, BFSI, healthcare, insurance, and real estate. The cause is not a lack of smart people. Someone is still keying in data that a machine could extract in seconds. This is a breakdown of what OCR software is, how it works, the categories it now falls into, and what to check before you pick one, organized around the actual reasons people go looking for it.
Who Actually Searches for OCR Software (and Why)
Before the mechanics, it is worth being specific about who ends up here, because "best OCR software" means something different depending on the answer:
- Freight and logistics teams processing bills of lading, proof of delivery, and carrier invoices by hand, usually at a volume where manual entry is now the bottleneck rather than the workaround. DeepRead's guide to freight broker software shows where document extraction fits in that workflow.
- Developers who have already tried an OCR API, such as Textract, Nanonets, or something built in-house, and hit an accuracy ceiling or spent weeks building workarounds instead of shipping.
- Ops and IT leads at high-volume enterprises (BFSI, healthcare, insurance, real estate) evaluating platforms like Rossum or UiPath, where the tool itself is capable but the implementation timeline and budget are the obstacle. DeepRead's overview of Rossum alternatives covers the options for teams in that position.
- Compliance and privacy teams doing PII detection and redaction manually today, with no audit trail, because most OCR tools do not treat compliance as a first-class feature.
- AI/ML and product teams who need OCR output to slot directly into an existing pipeline, with async processing, webhooks, and schema-driven JSON, not a UI to click through.
If you recognize yourself in one of these, skip ahead to "Types of OCR Software" and "What to Check Before Choosing." If you want the full picture first, keep reading.
What Is OCR Software?
Optical Character Recognition (OCR) software converts images of text, such as scanned pages, photographed documents, and image-only PDFs, into machine-readable, searchable, or structured data. Instead of a person retyping a scanned invoice or bill of lading, OCR software identifies the characters in the image and turns them into text a computer can process.
That is the narrow definition. The practical one, for anyone evaluating OCR software in 2026, is broader: modern OCR software does not just extract text, it extracts structure. It tells you not only what a document says, but what each piece of text means: this is an invoice number, this is a total, this is a shipper's signature block. That distinction is the difference between "we digitized our documents" and "we eliminated manual data entry," and it is the second one that actually moves cost and headcount.
How OCR Software Works
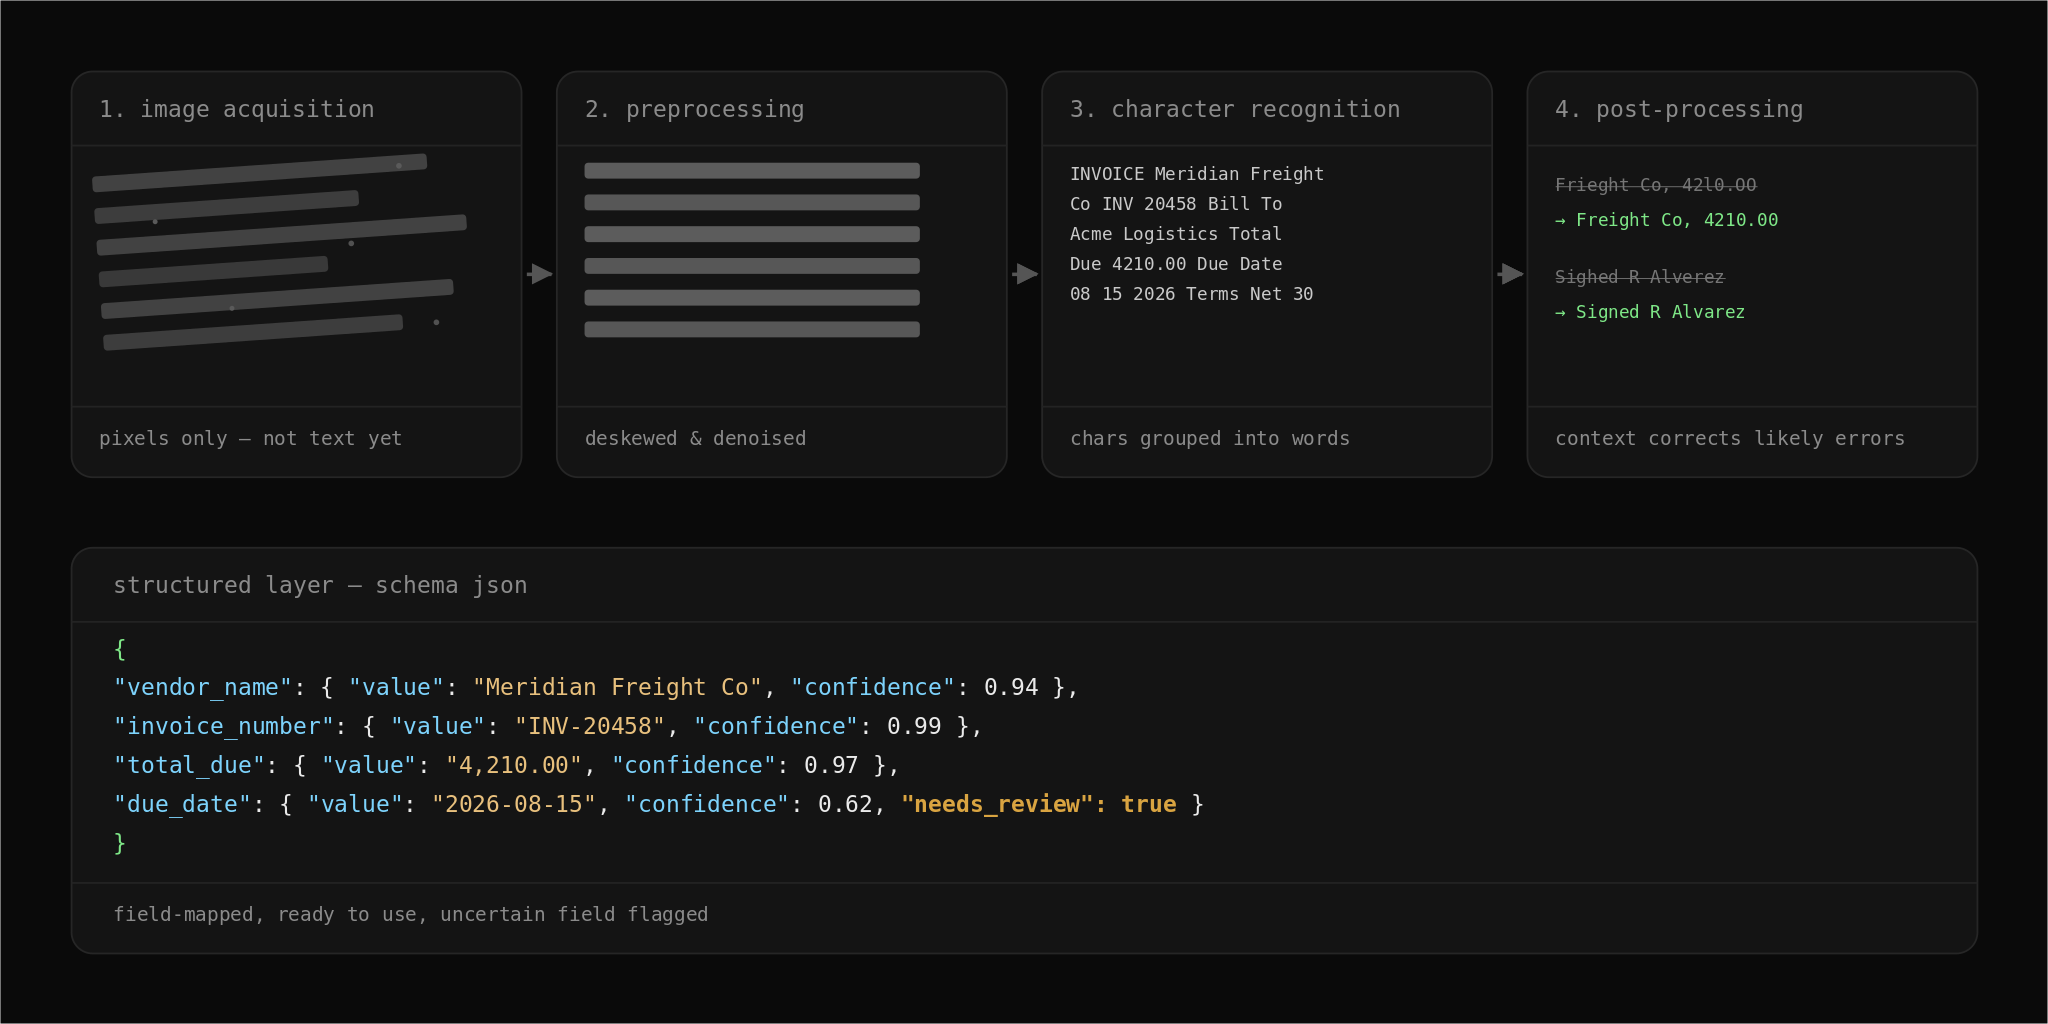
Most OCR pipelines, regardless of vendor, run through the same four stages:
- Image acquisition. The document page is captured or scanned and converted into a format the engine can analyze, typically reduced to light and dark regions.
- Preprocessing. The image is cleaned up: deskewing pages scanned at an angle, removing background noise, and stripping out lines and boxes that are not part of the actual text.
- Character and text recognition. The engine identifies dark regions as characters, groups characters into words, and words into lines and sentences.
- Post-processing. Contextual and language models correct likely errors, especially for irregular fonts or handwriting, before the final output is returned.
The more capable tools go a step beyond core OCR. They do not just return plain text. They return structured, schema-mapped JSON with field names, values, tables, and flags on values the system is unsure about, ready to drop into a database or downstream workflow without a human re-keying anything. This structured layer, covering classification, field mapping, and schema output, sits on top of OCR rather than being another OCR stage itself. For a developer, this is the entire ballgame: plain text means you are still writing parsing logic, and structured output means you are not.
Three Generations of OCR Software
Rules-based or traditional OCR relies heavily on pattern-matching and fixed rules. It is fast and low-cost, but can struggle with handwriting, unusual fonts, and layouts it was not tuned for. Tesseract is the best-known open-source engine, though modern versions (v4 and later) use neural network models, so it is no longer purely rules-based.
ML-based OCR layers machine learning on top of pattern matching, so the engine improves with exposure to varied layouts and fonts, and handles moderate handwriting and messier scans more reliably.
AI and LLM-native structured extraction is the current generation. Instead of just reading characters, these systems understand document layout and semantics, and output structured data directly, including field names, tables, and hierarchies, often without requiring a template or a model retrained per document type, though this varies by system and configuration. DeepRead's explainer on using LLMs for OCR covers how this approach works in practice. This is also where the developer pain point usually lives: tools that demand per-document-type training can break when a new invoice format or carrier layout shows up, which means someone is re-training a model instead of shipping.
Types of OCR Software (by Deployment)
- Open-source and self-hosted (Tesseract, PaddleOCR, EasyOCR). Best fit: teams wanting full control and no per-document fees. Trade-off: you maintain the infrastructure and accuracy tuning yourself.
- Desktop applications (Adobe Acrobat Pro, ABBYY FineReader). Best fit: non-technical users digitizing files manually. Trade-off: they are not built for automated, high-volume pipelines.
- RPA and enterprise platforms (UiPath Document Understanding, Rossum, which is now part of Coupa). Best fit: large enterprises with dedicated implementation budgets. Trade-off: longer deployment timelines and enterprise pricing, often with months before go-live.
- Developer OCR APIs (AWS Textract, Google Document AI, Nanonets, DeepRead). Best fit: teams building automated document workflows into their own product. Trade-off: they require engineering integration, but they scale without manual bottlenecks.
Two things are worth naming directly:
- If you are an ops or IT lead evaluating Rossum or UiPath, the trade-off is rarely capability. It is timeline and cost. Enterprise RPA platforms are built for teams that can absorb a long implementation cycle, while a developer OCR API with a free tier lets you validate accuracy on your own documents in days, not quarters.
- If you are a developer, the deployment type is not really a choice, because you are in API territory by default. What matters more at that point is whether the API handles batch volume asynchronously, so large document runs do not block or time out your application, and whether it returns schema-driven output you do not have to re-parse every time a layout changes.
What Actually Drives OCR Accuracy
"Accuracy" gets thrown around as a single number, but it is really a function of several things:
- Image quality. Clean, high-resolution scans are easy. Blurry, tilted, or low-light images, which are common in freight and field-collected documents, are not.
- Handwriting and non-standard formats. Most OCR tools were built and tuned for printed text. Handwritten fields and unconventional layouts are where accuracy commonly drops.
- Layout retention. Whether the engine preserves tables, columns, and field relationships, rather than returning a flat wall of text.
- Confidence handling. Whether uncertain extractions are flagged for a human to check, or silently returned as-is. This is the detail that separates tools in production from tools that look good in a demo: a system that fails silently on an uncertain field is worse than one that flags it, even if their raw accuracy scores look identical on paper. For any team running documents at volume, such as freight invoices or insurance claims, this is often the actual determinant of whether OCR software reduces ops load or just moves the error somewhere less visible. DeepRead returns uncertain values with a needs_review flag and a reason, and a review interface for flagged fields is available on every plan.
- Batch and scale handling. Whether the system can process large document batches asynchronously, without timing out or blocking the rest of your application. This matters specifically for AI/ML and product teams wiring OCR into an existing pipeline, where a blocking call on a 500-document batch is not a minor inconvenience. It is a broken workflow.
The honest way to evaluate any accuracy claim, including a vendor's own, is to ask what document set it was measured against, whether the methodology is public, and whether you can verify it yourself. DeepRead publishes its benchmark methodology, dataset breakdown, and results, including per-document-type accuracy, as one example of what a checkable claim looks like, rather than a number in a marketing slide. To compare language models on OCR tasks, see DeepRead's LLM OCR accuracy leaderboard.
Compliance and PII: Often the Part That Is Still Manual
For compliance and privacy teams, OCR software solves half the problem and creates the other half. Extracting structured data from a bank statement or medical bill also means that PII is now sitting in your system, and most OCR tools stop at extraction, leaving detection and redaction as a separate manual step. DeepRead's overview of automated document redaction tools explains how teams automate that step.
What to look for if this is your primary use case:
- Automated PII detection built into the extraction step, not bolted on afterward.
- Redaction that is automated and consistent, not manually applied per document.
- A workflow you can point to in an audit, rather than "we handle this case by case."
If PII handling is still a manual review step in your process today, that is usually the clearest sign the OCR tool you are evaluating was not built with compliance as a first-class requirement.
Where OCR Software Gets Used
- Freight and logistics: bills of lading, proof of delivery, carrier invoices.
- Banking and financial services: bank statements, loan documents, account-opening forms.
- Healthcare: medical bills, insurance claims, patient forms.
- Insurance: claims processing, policy documents.
- Real estate: leases, title documents, closing paperwork.
The common thread across all five is high document volume, non-standard layouts, and a direct, measurable cost to manual re-keying. That is why OCR adoption concentrates here rather than spreading evenly across every business type: the ROI is easiest to prove where the manual alternative is most visibly expensive.
What to Check Before Choosing OCR Software
- Independently verifiable accuracy. Not a marketing number, but a benchmark you can check against real documents and competing tools, with a published methodology behind it.
- Compliance and PII handling. Especially for regulated data like medical bills, bank statements, or ID documents.
- Human-in-the-loop fallback. Does uncertain output get flagged, or does it fail silently?
- Integration path. REST APIs, SDKs, and webhooks if you are building this into a product, async support if you are processing documents in batches, and a GUI only if you are not technical. Check the provider's own documentation for the specifics rather than relying on a sales page.
- Deployment speed. Can you be live in days, or is this a quarter-long enterprise rollout?
- Pricing and trial access. Can you test the tool against your own documents before committing, or is pricing gated behind a sales call?
Conclusion
There is no single "best" OCR software. There is the right OCR software for what is actually costing you time or money. A freight team drowning in BOLs needs volume and speed more than a fancy UI. A developer who has already hit an accuracy wall needs an API that returns clean, schema-driven JSON without demanding a model retrain every time a layout shifts. A compliance team needs automated PII detection and redaction built in, not bolted on. And an enterprise stuck evaluating Rossum or UiPath usually is not questioning capability. It is questioning whether they can afford the timeline.
The through-line across all of it is that accuracy claims are only as useful as the methodology behind them. Whatever you choose, test it against the messiest, most representative document you actually process, not a clean sample PDF, and ask for a public benchmark, not just a headline number, before you commit budget or engineering time to it.
Frequently Asked Questions
Is OCR the same as AI?
Not inherently. Traditional OCR was originally pattern matching rather than AI, though most modern engines, including open-source ones like recent Tesseract versions, now use neural network models. "OCR" itself just refers to the task of extracting text from images, regardless of the underlying method.
What is the difference between OCR, ICR, and IDP?
OCR reads printed text. ICR (Intelligent Character Recognition) extends that to handwriting. IDP (Intelligent Document Processing) is the broader category. It includes OCR and ICR as one step, plus classification, structured data extraction, and workflow automation on top.
How is an OCR API different from a platform like Rossum or UiPath?
Capability-wise, they can overlap. The practical difference is deployment: RPA and enterprise platforms are usually built around a longer implementation process and enterprise contracts, while a developer OCR API is built to integrate directly into your existing product or workflow, often testable within days on a free tier rather than requiring a sales cycle first. See a provider's API documentation directly to compare integration effort.
Can OCR software handle PII detection and redaction automatically?
Some can, most cannot. Basic OCR tools extract data and stop there, leaving PII detection and redaction as a manual downstream step. If audit-ready compliance matters to you, this needs to be a specific evaluation criterion, not an assumption.
Is there free OCR software?
Yes, both open-source engines (Tesseract, PaddleOCR) and free tiers from commercial OCR APIs, though free tiers usually cap monthly document volume. Check current terms on the provider's pricing page, since these change.
How accurate is OCR software, really?
It depends heavily on document type and tool, and it is worth asking for a specific, verifiable answer rather than a general one. DeepRead's published benchmark, for example, measures accuracy across eight document types (invoices, medical bills, payslips, bank statements, insurance forms, W-2s, driver's licenses, and offer letters) against a fixed ground-truth dataset, with results and methodology public at deepread.tech/benchmarks. Whichever tool you are evaluating, ask the same question: what was this measured against, and can you check it yourself?
More articles
Semantic Document Search: How It Works and How to Build It with Embeddings
How semantic document search works, plus a Python build: extract, chunk, embed, and search, with a tested keyword, semantic, and hybrid comparison.
How to Parse a PDF File: Methods, Libraries, and Tools
Parse a PDF file in Python with tested code: check the text layer, extract text and tables, OCR scanned pages, and compare pypdf, pdfplumber, and PyMuPDF